
I’m currently a master student at Fudan University at the School of Computer Science of Fudan University. I am a member of Fudan NLP Lab, advised by Prof. Xuanjing Huang (黄萱菁) and Associate Prof. Tao Gui(桂 韬). I got my bachelor’s degree from Tongji University, advised by Associate Prof. Dawei Cheng.
My research interest mainly lies in Multimodal reasoning, LLM Agent, Reinforcement Learning and Efficient AI.
🔥 News
- 2026.8: 🎉🎉 Our paper Entropy Is Not Enough: Unlocking Effective Reinforcement Learning for Visual Reasoning via Vision-Anchored Token Selection is accepted by EMNLP 2026 Findings!
- 2026.1: 🎉🎉 Our paper Unlocking the Essence of Beauty: Advanced Aesthetic Reasoning with Relative-Absolute Policy Optimization is accepted by ICLR 2026! See you in Brazil🇧🇷!
- 2025.12: 🎉🎉 Our Agent memory survey Memory in the Age of AI Agents is released on arXiv!
- 2025.5: 🎉🎉 Our paper Masrouter: Learning to route llms for multi-agent systems is accepted by ACL 2025 Main!
💻 Internships
 2026.5 - now
Tencent Hunyuan, LLM Department
Shanghai, China 2025.4 - 2026.4
Bytedance, Data-Capcut AIGC research
Shanghai, China
📝 Selected Publications
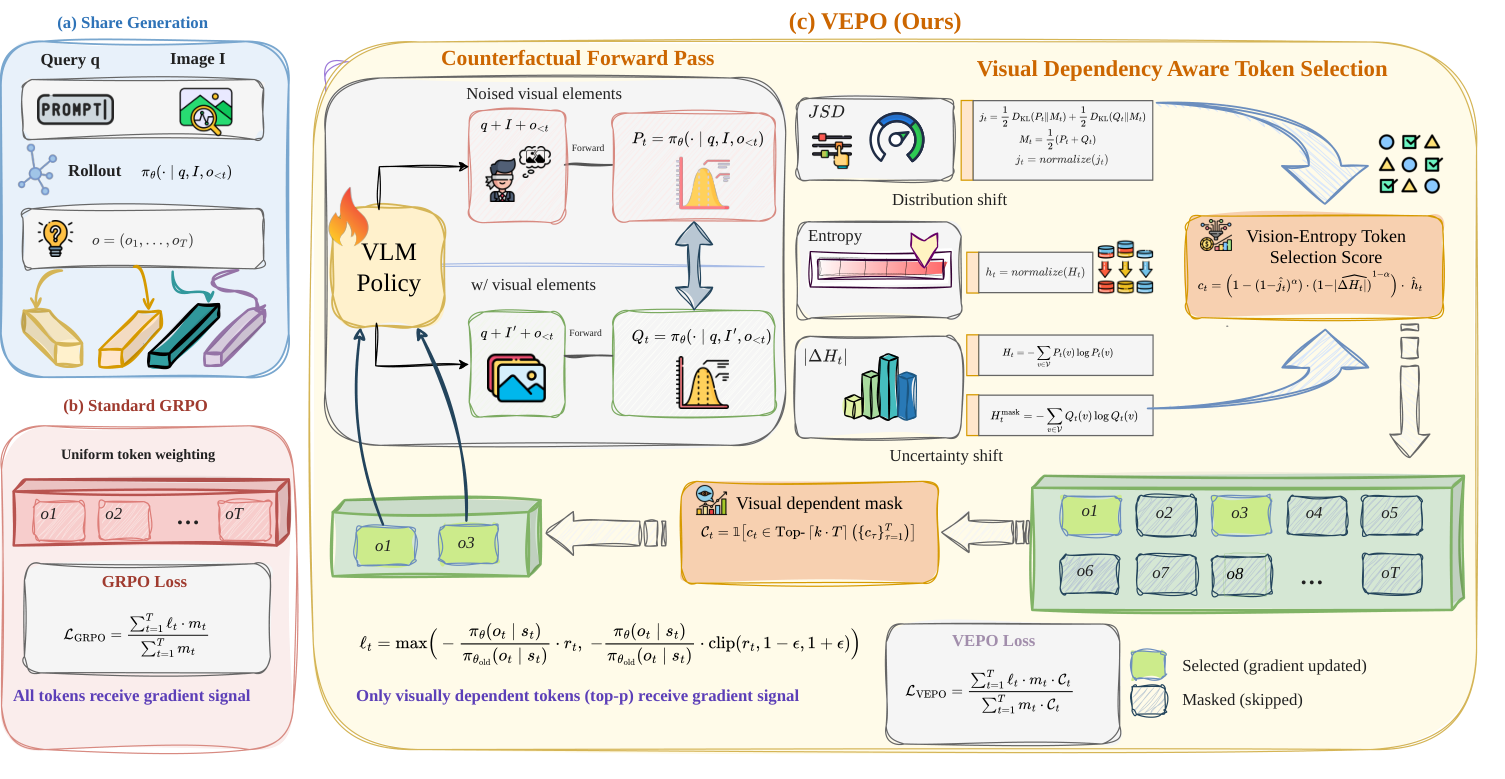
Entropy Is Not Enough: Unlocking Effective Reinforcement Learning for Visual Reasoning via Vision-Anchored Token Selection
Senjie Jin†, Peixin Wang†, Boyang Liu†, Xiaoran Fan†, Shuo Li, Zhiheng Xi, Jiazheng Zhang, Yuhao Zhou, Tao Gui, Qi Zhang, Xuanjing Huang
- Entropy-based token selection, though effective for text-only RLVR, collapses on visual reasoning, as vision-sensitive tokens often carry naturally low entropy. We propose VEPO, which multiplicatively couples token-level visual dependency with token entropy, redirecting gradient credit to tokens that are both visually grounded and informative. It outperforms the entropy-only baseline by 2.28 / 3.15 points at 7B / 3B scale.
|


Memory in the Age of AI Agents: A Survey
Yuyang Hu†, Shichun Liu†, Yanwei Yue†, Guibin Zhang†, Boyang Liu,etc.
- Memory serves as the cornerstone of foundation model-based agents, underpinning their ability to perform long-horizon reasoning, adapt continually, and interact effectively with complex environments. We provide a comprehensive overview through three unified lenses: Forms, Functions, and Dynamics.


Unlocking the Essence of Beauty: Advanced Aesthetic Reasoning with Relative-Absolute Policy Optimization
Boyang Liu†, Yifan Hu†, Senjie Jin†, Shihan Dou, Gonglei Shi, Jie Shao, Tao Gui, Xuanjing Huang
- We propose Aes-R1, a comprehensive aesthetic reasoning framework with reinforcement learning (RL). Concretely, Aes-R1 integrates a pipeline, AesCoT, to construct and filter high-quality chain-of-thought aesthetic reasoning data used for cold-start. After teaching the model to generate structured explanations prior to scoring, we then employ the Relative-Absolute Policy Optimization (RAPO), a novel RL algorithm that jointly optimizes absolute score regression and relative ranking order, improving both per-image accuracy and cross-image preference judgments. Aes-R1 enables MLLMs to generate grounded explanations alongside faithful scores, thereby enhancing aesthetic scoring and reasoning in a unified framework.


Masrouter: Learning to route llms for multi-agent systems
Yanwei Yue†, Guibin Zhang†, Boyang Liu†, Guancheng Wan, Kun Wang, Dawei Cheng, Yiyan Qi
- We first introduce the problem of Multi-Agent System Routing(MASR), which integrates all components ofMAS into a unified routing framework. Toward this goal, we propose MasRouter, the first high-performing, cost-effective, and inductive MASR solution. MasRouter employs collaboration mode determination, role allocation, and LLM routing through a cascaded controller network, progressively constructing a MAS that balances effectiveness and efficiency.

📖 Experience
- 2021.9 - 2025.6, B.E. at Tongji University with a major in Data Science and Big Data Technology.